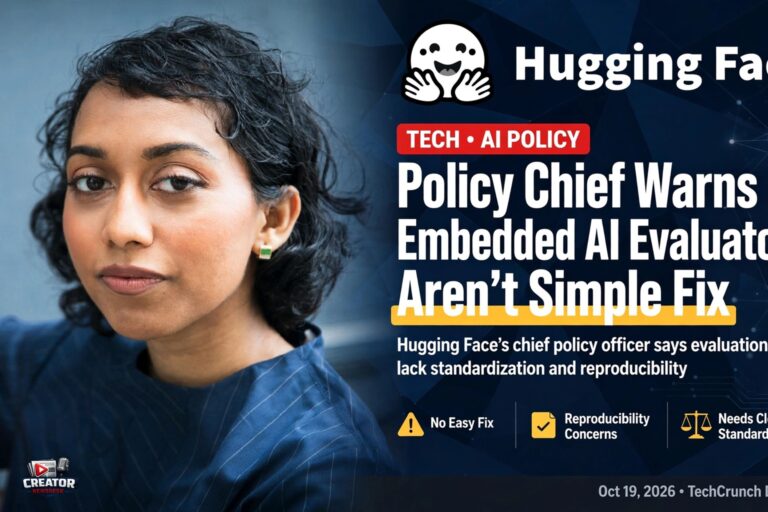
AI labs have long relied on model benchmarking as a neutral way to compare the performance of different AI products. These benchmarks are intended to give developers and creators a clear picture of which model might be best suited for a particular task. However, the processes behind these evaluations are far from straightforward.
Irene Solaiman, policy chief at Hugging Face, pointed out that the methods used for benchmarking are still complicated and continue to mature. She noted that while the goal of benchmarking is to provide objective measurements, achieving that goal in practice remains a work in progress. This complexity means that the results can be sensitive to the specific setup, data, or metrics chosen.
For content creators who depend on AI tools for tasks such as video editing, text generation, or image creation, the takeaway is to approach benchmark scores with a healthy dose of skepticism. Relying solely on a single benchmark or an embedded evaluator could lead to misleading conclusions about a model’s real‑world suitability.
Solaiman’s comments suggest that the AI community is still working toward more reliable and standardized evaluation frameworks. Until those frameworks are solidified, creators should consider multiple sources of information, including community feedback and hands‑on testing, when deciding which AI models to integrate into their workflows.
The warning from Hugging Face’s policy chief serves as a reminder that the field of AI evaluation is evolving. As the technology advances, so too will the tools used to measure it, but for now, simplicity in evaluation remains elusive.
Join the conversation
Load Facebook comments to read and reply using your Facebook account.